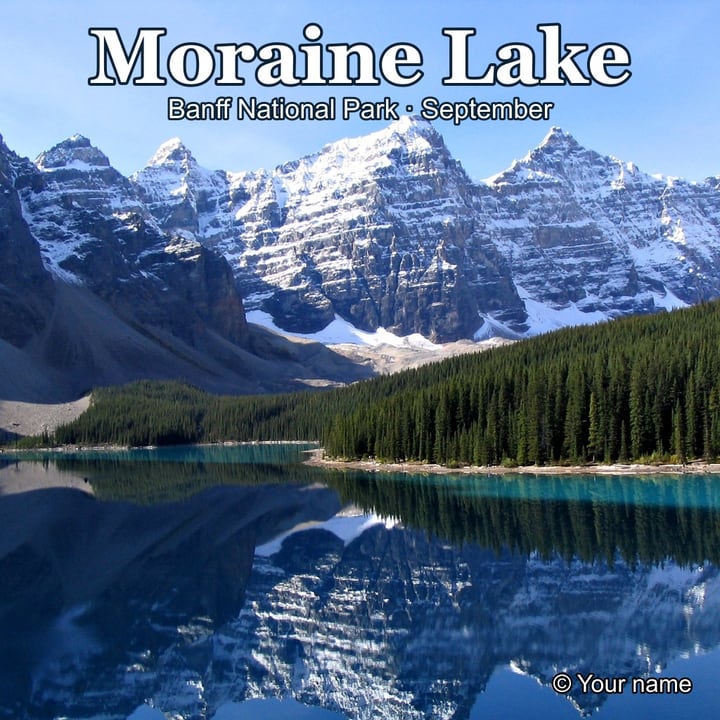

How to remove text from an image
- Add the picture. Drop it anywhere on the page, paste it, or click the box to choose a file. Phone photos, including iPhone HEIC, work too.
- Press Find the text. The first time, the page downloads a small text detector (4.6 MB) and your browser keeps it. Finding the text took about half a second on our test computer, for pictures from 800 to 3200 pixels. Everything it found is shown in red.
- Check the marks. Paint over text adds anything it missed, Erase a mark takes a mark off something that should stay (a sign that is part of the scene, for example), Undo stroke and Clear marks work as you would expect. Three sliders change the marks without searching again (see below).
- Press Remove the text. The first time, the page downloads a filling-in model (27 MB for Fast, 208 MB for Best quality) and your browser keeps it. Switch the view to Original to compare. If you do not like it, Undo last removal brings the picture back (the last three are kept).
- Download the picture. It is saved at its full size as a JPG, PNG or WebP, named after your file with
-removedadded.
Your original file is never changed. After a removal you can press Find the text again: it looks at the picture as it is now, so it finds anything that is left.
What it finds
The page does not read the words. It looks for where text is, with PP-OCRv5 mobile text detection, a small network from the PaddleOCR project (Apache-2.0). It looks at your picture at about 960 pixels on the longer side and answers, for each spot, how likely it is to be part of a line of text. The likely spots are grouped into one piece per piece of text, and each piece is made bigger by a margin, because the answer is a thin core that is smaller than the letters really are. Because it looks for the shape of writing and not for letters of one alphabet, it does not need a language setting: it found Japanese, Cyrillic and Arabic lines in our tests as readily as English ones. It handles light text on a dark background, outlined and shadowed text, text at an angle and watermarks across the middle of a picture.
It marks all the text, including text that is part of the scene: a shop sign, a number plate, a badge on a car. That is why the marks are shown for you to check before anything is removed.
The settings
| Setting | What it changes |
|---|---|
| Look for | Normal text looks at the picture at 960 pixels on the longer side. Small text looks at 1600 pixels, which finds writing that is only a few pixels tall at 960, takes about 1.3 seconds instead of 0.5 on our test computer, and marks more small specks that are not text (see below). It runs the detector again. |
| Certainty | How sure the detector must be before a piece is marked. At 50% (the starting value, the detector's own setting) a piece needs an average score of 0.6 out of 1; at 0% anything it found is marked, at 100% only the most certain pieces. Raise it if there are red marks on things that are not text. |
| Margin | How far the marks reach past the letters, from 0 to 100% (50% is the detector's own setting). On a photo with a large title the marks covered 10% of the picture at Margin 0, 18% at 50% and 27% at 100%, while the letters themselves were 14%. A bigger margin catches the soft edge of letters, shadows and outlines; a smaller one gives the model less to rebuild. |
| Cover the edges | The same slider as in Remove Object (0 to 20, starting at 4): it grows what is marked by a few more pixels before filling it in. |
Moving Certainty or Margin redraws the red marks from the same answer, in a moment, without searching again. Whatever you painted or erased afterwards stays as you left it. Clear marks removes the marks; pressing Find the text brings them back.
Fast or Best quality?
The filling-in step is the same as in Remove Object. Fast (MI-GAN, 27 MB) takes 2 to 6 seconds on an 800 × 800 picture. It is clean over a meadow or plain sky, but over detail it smears: in our tests it smudged the reflection in a lake, left a faint box in the sky around the place where a sign had been, and drew a streak out of the tip of a fox's ear. Best quality (LaMa, 208 MB) was cleaner on all of those, and took about 20 seconds for each area it fills (1 area: 22 seconds; 2 areas: 38; 4 areas: 71). Text that is close together is filled in together, and text far apart is filled in separately, area by area; the status line says how many. Try Fast first, and use Best quality if you see a smear.
What we measured
We drew text on photos ourselves (so that the clean photo is the exact answer), found it with the page, and removed it with the real models:
- The marks cover the text. On six pictures (a meme-style title at the top and bottom, a yellow subtitle, a white sign in two sizes, a diagonal semi-transparent watermark, a date stamp, and a script-font greeting) the starting settings marked 99.5 to 100% of the text pixels, 99.9% on average. The marks cover 1.3 to 4 times the area of the letters themselves, because of the margin.
- Other writing systems. A picture with Japanese, Cyrillic and Arabic lines: all three lines were found, 100% of the text pixels marked.
- Small print needs Small text. On a 3200-pixel picture with 22-pixel writing (a credit line, a place name, a faint copyright line), Normal text marked about half of it (49%), and Small text 99.8%. With 30-pixel writing Normal text already found all of it.
- It finds real text too. On the date stamp picture it also marked the car's badge and number plate, which are really in the photo.
- It sometimes marks things that are not text. On six photos with no text we added, Normal text marked nothing on two of them, one spot on a bird's tail, three on the hinges of a pair of headphones, three on a street (a shop sign, which is real text, and wall stains) and 20 tiny specks on a bicycle's frame, at most 0.64% of the picture each time. Small text finds more of these: up to 110 specks on the bicycle, still under 1% of the picture. This is why you check the marks.
- Only the marks change. After a removal, not one pixel more than 40 pixels from the marks was different from the original. The fill reaches a few pixels beyond the marks (the Cover the edges setting plus a soft blend), and no further.
- How close it gets to the real picture. We measured the average difference (0 to 255) between the text pixels and the clean photo underneath. The picture with text on: 87. After Fast: 19.0. After Best quality: 15.9. A classic fill that has no model in it (the Telea method in OpenCV) on the same marks: 19.3. So on this plain measure Fast was no better than the classic fill and Best was 18% closer. A pixel difference does not show how natural a fill looks, which is why the pictures on this page are the better test.
- Why not read the text with an OCR engine? We tried it first, with the engine of Image to Text, boxing every word. On the same pictures it marked between 0% and 61% of the text and most of what it marked was not text, because an OCR engine is built to read a clean page, not to find writing on top of a photograph.
What works well, and what does not
- Works well: text over sky, water, snow, walls, blurred backgrounds, smooth skin or fur; captions, subtitles, date stamps, a title, a diagonal watermark across grass or trees. With Best quality such text vanished with no visible trace at normal size in our tests; Fast did the same over the meadow and the sky, but not over detail.
- The fill is a guess. Where the text lay over something with structure, the model draws what it thinks was there. In our tests a title that touched the peak of a mountain left the summit slightly softer than the real one; a lantern at the top of a lighthouse that the text had covered came back as a plausible lantern of a different shape; a greeting across a kitten's ear left a smudge where the tip of the ear had been; and a caption over a fox's ear left a small green speck (Best) or a streak (Fast). Look at the result at full size before you use it.
- Text over faces, hands, logos and fine patterns cannot be recovered: nothing in the picture says what was underneath.
- Very decorative lettering is the least reliable to find. On its own model card the detector's lowest scores are for artistic text, Pinyin and ancient writing. Paint over what it misses.
- Handwriting and strongly turned text scored lower than printed lines on the detector's own model card. Our watermark slanted at 25 degrees was found completely, but check the marks.
- A few letters left behind. If a thin line of a letter is left outside the marks, it is treated as part of the picture and continued. Raise Margin or the Cover the edges slider, or paint over it.
Use it on your own pictures
This tool is for pictures you own or may edit: a caption or a date you no longer want on your own photo, text you added and lost the clean file of, a screenshot you want to tidy. It is not a way to take the credit, the name or the watermark off someone else's work. Removing text does not give you the right to use a picture, and the owner decides that. For a watermark in particular, see Watermark Remover and our guide on content credentials and watermarks.
Size, speed and limits
- Size. Your picture is worked on and saved at its full size. A picture over 24 megapixels is made smaller when it is opened, and the page says so. See-through areas become white.
- Speed. Finding the text takes about half a second per picture once the 4.6 MB detector is loaded (1.3 seconds with Small text). The fill takes 2 to 6 seconds with Fast and about 20 seconds per area with Best quality at 800 × 800. Big pictures are slower, and phones and older computers much slower.
- Memory. The Best quality model needs a lot of memory. If it fails on your device, use Fast.
- One picture at a time. The marks belong to a particular picture.
- The fill is made at 512 pixels. The model fills a square window around each piece at 512 × 512 and the result is scaled back, so a very large piece of text on a large picture is filled in softer than the photo. Mark text in pieces if that happens.
Where the work happens
- Everything runs inside this tab. The page downloads the models from Hugging Face the first time you use them: PP-OCRv5 mobile text detection (Apache-2.0) to find the text, and MI-GAN (MIT) or LaMa (Apache-2.0) to fill it in. See Credits. Your file on disk is never changed or deleted.
- For what this site collects and keeps, see our privacy policy.
Frequently asked questions
How do I remove text from a picture?
Add the picture, press Find the text, check the red marks (paint over anything missed, erase a mark that should stay), then press Remove the text. The marked parts are filled in from the picture around them.
Does it work on any language?
It looks for the shape of writing, not for letters of one alphabet, so there is no language setting. In our test it found English, Japanese, Cyrillic and Arabic lines. It does not read the text.
Why did it mark something that is not text?
The detector sometimes takes a pattern for writing: a feather, a hinge, a stain on a wall, the strings of a fence. That is why the marks are shown first. Erase them with Erase a mark, or raise Certainty so that only the most certain pieces are marked.
Why did it miss some small text?
Normal text looks at the picture at 960 pixels on the longer side, so writing a few pixels tall on a big photo is too small to see. Choose Small text in Look for and press Find the text again, or paint over the text.
Can it remove a watermark?
It finds and removes a watermark that is made of text and sits on a picture you own, such as a name you stamped on your own photo. It cannot remove a hidden or invisible mark, and it is not for taking the watermark off other people's work. See Watermark Remover for brushing over a logo.
Why does the filled area look different from the rest of the picture?
The model draws what it thinks was under the text, and it works at 512 pixels, so a large filled area can be softer or smoother than a sharp photo, and fine patterns and straight edges can bend. Use Best quality, mark the text in smaller pieces, or lower Margin so that less has to be rebuilt.
Does it change the rest of my picture?
No. In our test not one pixel farther than 40 pixels from the marks was different afterwards. The fill reaches a few pixels beyond the marks and fades into the picture.
Is my picture sent anywhere to remove the text?
The text is found and filled in inside your browser tab; the models are downloaded to it. For what the site collects and keeps, see our privacy policy.